Abstract
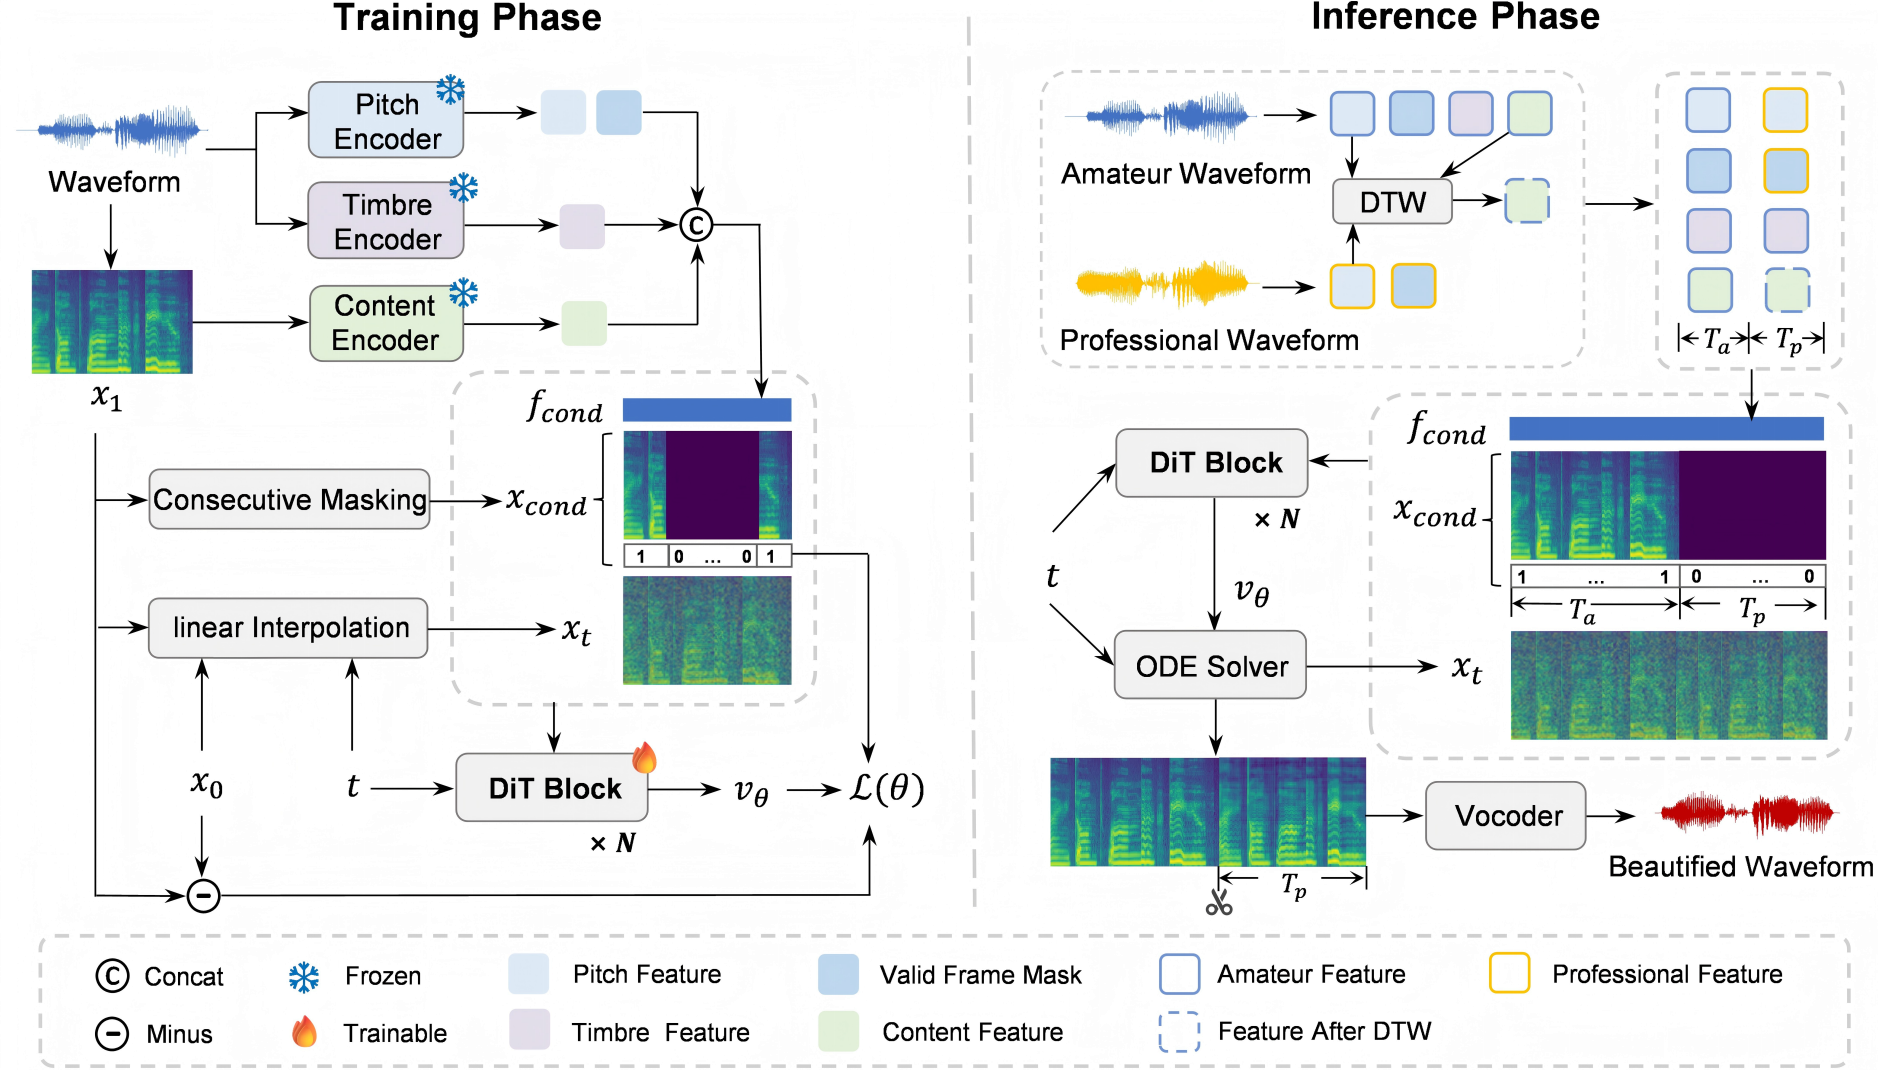
Singing voice beautifying (SVB) aims to correct pitch and rhythm of amateur singing while enhancing vocal quality, preserving lyrics and the singer's timbre. Existing methods, however, suffer from limited generation quality and efficiency, and tend to neglect the preservation of the singer's style. We propose SRF-SVB, a style-consistent model for SVB via rectified flow, which achieves high-fidelity and efficient beautification covering pitch and rhythm correction. Furthermore, we design a context-guided masked mel-spectrogram inpainting mechanism that effectively preserves the amateur singer's style, including unique timbre and expressive patterns. Experiments on both English and Chinese test sets show that SRF-SVB outperforms baseline models in most objective and subjective metrics.
Model Architecture
Audio Samples
我们一共选择了12个音频样例进行展示,包含中英文和男女性。
Chinese
男声1:
| Amateur | Professional | DiffPitcher | NSVB | SRF-SVB |
|---|---|---|---|---|
男声2:
| Amateur | Professional | DiffPitcher | NSVB | SRF-SVB |
|---|---|---|---|---|
男声3:
| Amateur | Professional | DiffPitcher | NSVB | SRF-SVB |
|---|---|---|---|---|
女声1:
| Amateur | Professional | DiffPitcher | NSVB | SRF-SVB |
|---|---|---|---|---|
女声2:
| Amateur | Professional | DiffPitcher | NSVB | SRF-SVB |
|---|---|---|---|---|
女声3:
| Amateur | Professional | DiffPitcher | NSVB | SRF-SVB |
|---|---|---|---|---|
English
男声1:
| Amateur | Professional | DiffPitcher | NSVB | SRF-SVB |
|---|---|---|---|---|
男声2:
| Amateur | Professional | DiffPitcher | NSVB | SRF-SVB |
|---|---|---|---|---|
男声3:
| Amateur | Professional | DiffPitcher | NSVB | SRF-SVB |
|---|---|---|---|---|
女声1:
| Amateur | Professional | DiffPitcher | NSVB | SRF-SVB |
|---|---|---|---|---|
女声2:
| Amateur | Professional | DiffPitcher | NSVB | SRF-SVB |
|---|---|---|---|---|
女声3:
| Amateur | Professional | DiffPitcher | NSVB | SRF-SVB |
|---|---|---|---|---|